Research
My research includes algorithmic optimization of Large Language Models (LLMs) and hardware implementations of Convolutional Neural Networks (CNNs) and LLMs.
Specifically, I worked on KV-cache compression for long-context reasoning tasks of LLMs and CUDA kernel development for efficient LLM inference.
I also work on hardware-friendly deployment of CNN keyword-spotting models, implementation of Verilog RTL codes for machine learning accelerators, and contributed to the Tape-Out of CNN accelerators.
📦 Algorithm Level
KV-cache quantization and GPU inference
- Developed adaptive KV-cache quantization and tile-level precision control for LLM inference, co-designing quantization policies with memory bandwidth and hardware dataflow constraints to reduce KV memory traffic while preserving model quality.
CUDA Kernel Development for Fast Matrix Multiplication
- Built optimized CUDA kernels for LLM inference leveraging block tiling, vectorized memory access, shared-memory reuse, warp-level tiling, and Tensor Core WMMA instructions. Reached near-PyTorch training/inference performance. link
📦 Algorithm-Hardware Co-Design
FPGA LLM deployment
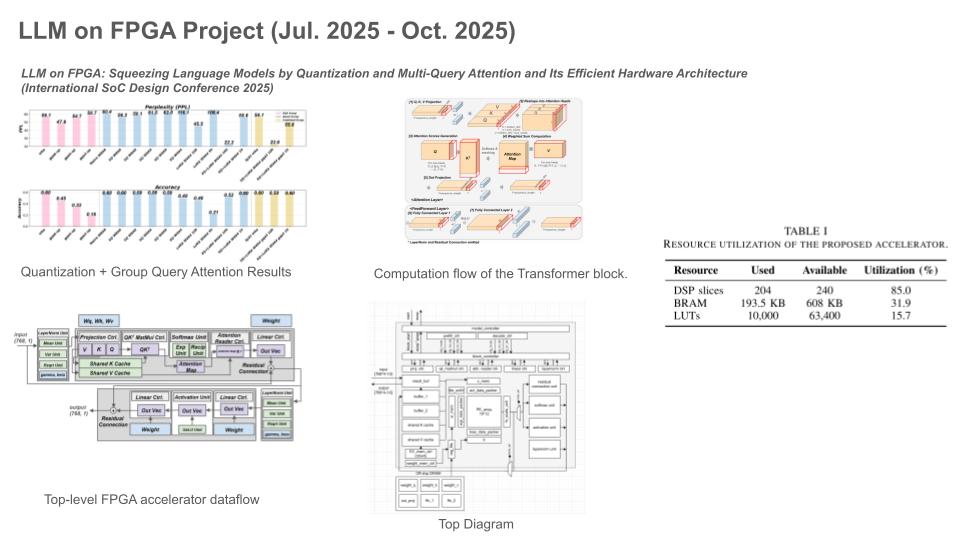
- Implemented Multi-Query Attention and W4A4 for FPGA LLM deployment; designed RTL in SystemVerilog for Transformer blocks; conducted synthesis and bitstream generation for FPGA implementation in Xilinx Vivado. link
📦 Hardware & Circuit Level
Tape-out of CNN Accelerator for Keyword Spotting and Speaker Verification ASIC
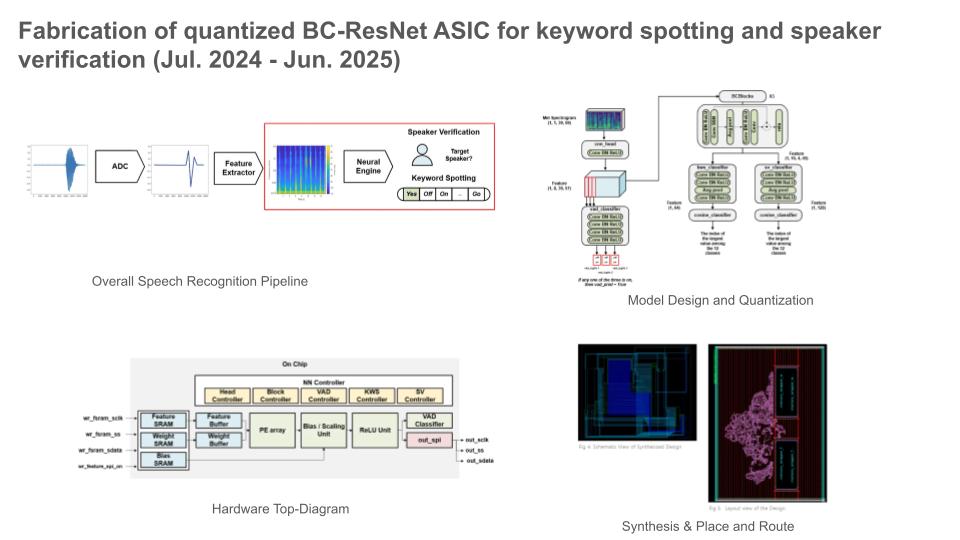
Fine-tuned CNN keyword-spotting (KWS) models for hardware-friendly deployment using framewise incremental computation scheme; designed Verilog RTL blocks for efficient CNN operations. Participated in the Multi-Project Wafer (MPW) program for undergraduate and graduate students organized by IDEC and contributed to the tape-out of KWS ASIC tape-out. link
Quantized BC-ResNet for keyword spotting (KWS) and speaker-verification(SV) embeddings; implemented PTQ/QAT (CLE, bias correction, AWQ, SmoothQuant, PACT). Participated in the Multi-Project Wafer (MPW) program organized by IDEC and contributed to KWS and SV ASIC tape-out. link
Capstone Design Project on CNN Hardware Accelerator for SubPixel Rendering
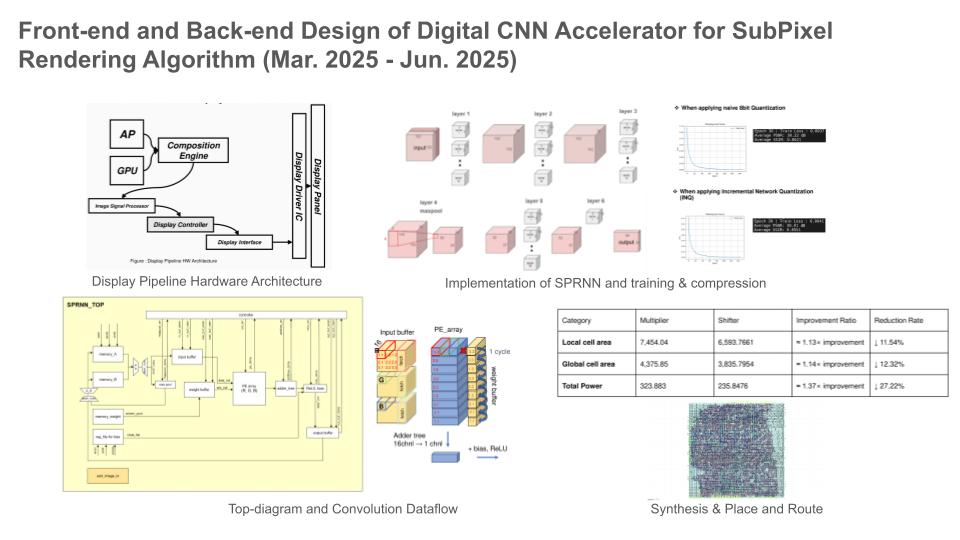
Led a team of four undergraduates to implement and train a CNN-based subpixel rendering algorithm, optimizing network parameters using Incremental Network Quantization scheme.
Designed its hardware accelerator in Verilog: developed a pipelined structure and validated its functionality.
Executed the full digital ASIC tape-out flow, including RTL synthesis, timing-driven place-and-route, power and timing sign-off, and final GDSII generation. Awarded Engineering Innovation Prize.
📦 Others: Intelligent Sensing and Fault Diagnosis
Developed a 1D-CNN LSTM–based fault diagnosis system for rotating machinery using vibration and acoustic signals, achieving up to 97.4% classification accuracy across multiple fault conditions.
Utilized time-series feature extraction and sequence learning techniques to detect mechanical anomalies such as mechanical looseness, improving predictive maintenance capability.